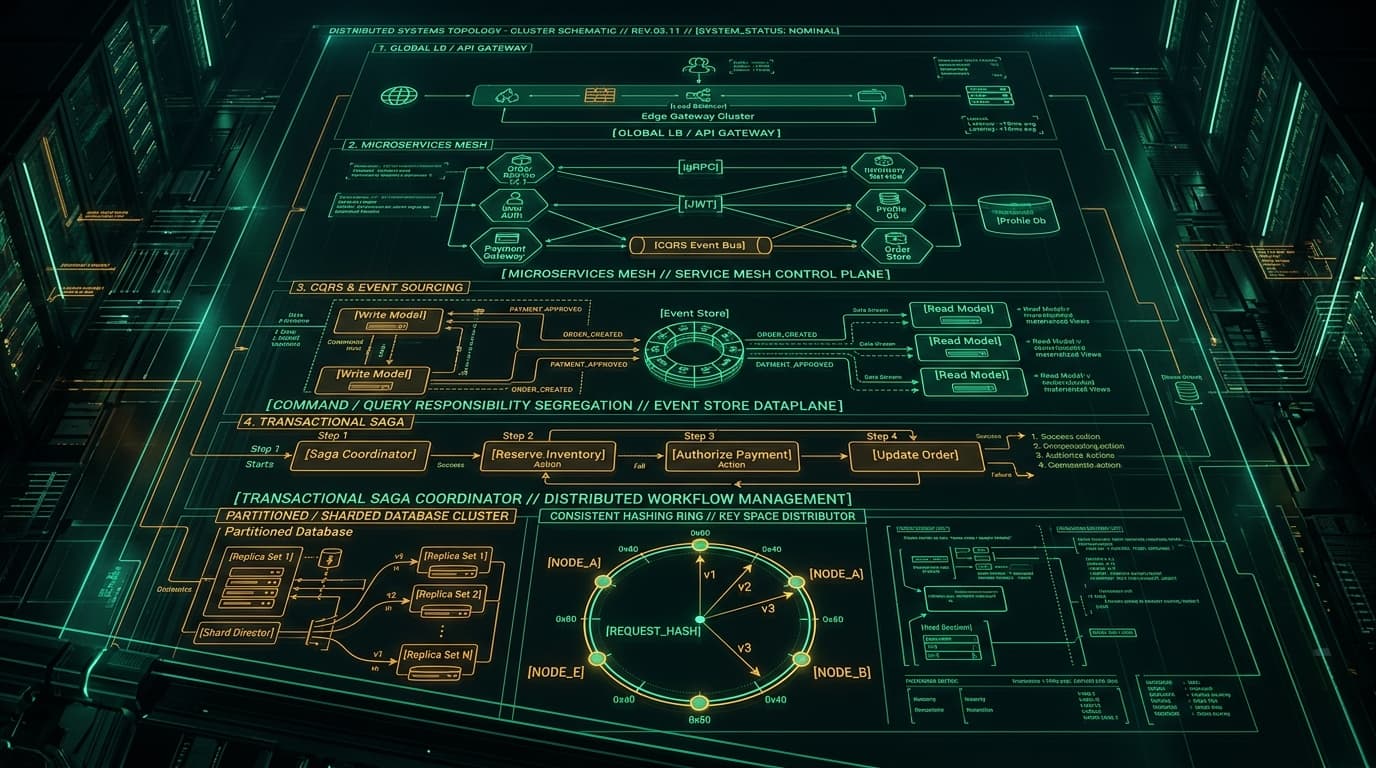
> STORAGE_PARTITIONING // Gossip // AP
Dynamic Consistent Hash Ring with Virtual Node Rebalancing
High-scale dynamic data partitioning ring utilizing consistent hashing with virtual nodes (vnodes) to achieve uniform key distribution and minimal data migration during node scaling.
Problem Statement & Architectural Hypothesis
Modulo-based sharding (`hash(key) % N`) forces a complete, catastrophic reshuffle of 100% of data across all servers whenever a single node is added or removed.
Formal Distributed Guarantees
- ⚡Only $K/N$ keys moved on node addition or removal (minimal disruption)
- ⚡Uniform partition balance via 256 virtual nodes per physical machine
- ⚡$O(\log N)$ binary search routing latency
Handled Failure Modes
3 Maturity & Scale Configurations
Step-by-step production configurations from single-cluster baseline up to multi-datacenter ultra-scale.
10,000 lookups/sec
< 5ms
Stateless Application-Layer Hash Ring
Client libraries maintain an identical in-memory hash ring with MurmurHash3.
150,000 lookups/sec
< 1.8ms
Stateful VNode Ring with Dynamic Gossip Protocol Membership
Ring cluster with 256 vnodes per host, gossip failure detection, and automatic hint handoff.
2,500,000 lookups/sec
< 0.6ms
Bounded-Load Consistent Hashing (Mirrokni Algorithm)
eBPF kernel bypass layer evaluating consistent hash ring directly on incoming network packets.
Infrastructure as Code: Terraform, Kubernetes & Engine Configs
Production-ready automation manifests ready for deployment on Kubernetes and cloud providers.
resource "aws_security_group_rule" "cassandra_gossip" {
  type              = "ingress"
  from_port         = 7000
  to_port           = 7000
  protocol          = "tcp"
  self              = true
  security_group_id = aws_security_group.ring_nodes.id
}apiVersion: v1 kind: ConfigMap metadata: name: ring-config data: NUM_TOKENS: "256" ENDPOINT_SNITCH: "GossipingPropertyFileSnitch"
num_tokens: 256
initial_token: null
partitioner: org.apache.cassandra.dht.Murmur3Partitioner
commitlog_sync: periodic
commitlog_sync_period_in_ms: 10000
High-scale dynamic data partitioning ring utilizing consistent hashing with virtual nodes (vnodes) to achieve uniform key distribution and minimal data migration during node scaling.
Architecture Blueprint FAQs
What is the mathematical CAP and PACELC classification of Dynamic Consistent Hash Ring with Virtual Node Rebalancing?
Dynamic Consistent Hash Ring with Virtual Node Rebalancing is classified under CAP as AP and under PACELC as PA/EL. During network partitions, it prioritizes availability, maintaining strict state guarantees.
How does the Gossip consensus protocol operate in this architecture?
This blueprint relies on Gossip for quorum-based state machine replication. Leader election, log compaction, and split-brain prevention are enforced through monotonic terms and fencing tokens.
Which distributed failure modes does this architecture handle?
The architecture explicitly handles the following failure modes: DS-FAIL-12: Hot Partition Skew, DS-FAIL-20: Gossip Protocol Convergence Lag, ensuring no silent divergence or message loss.
What are the throughput and latency differentials between Initial and Ultra-Scale tiers?
The Initial tier targets 10,000 lookups/sec with < 5ms p99 latency (Client libraries maintain an identical in-memory hash ring with MurmurHash3.), whereas Ultra-Scale scales to 2,500,000 lookups/sec with < 0.6ms (eBPF kernel bypass layer evaluating consistent hash ring directly on incoming network packets.) using: Custom C++/Rust Proxy, eBPF XDP Routing, Aerospike Cluster.
How is this architecture provisioned via declarative Infrastructure as Code?
The provided Terraform HCL, Kubernetes manifest, and engine configuration properties furnish immediate production templates for Kubernetes clusters and event broker topologies.