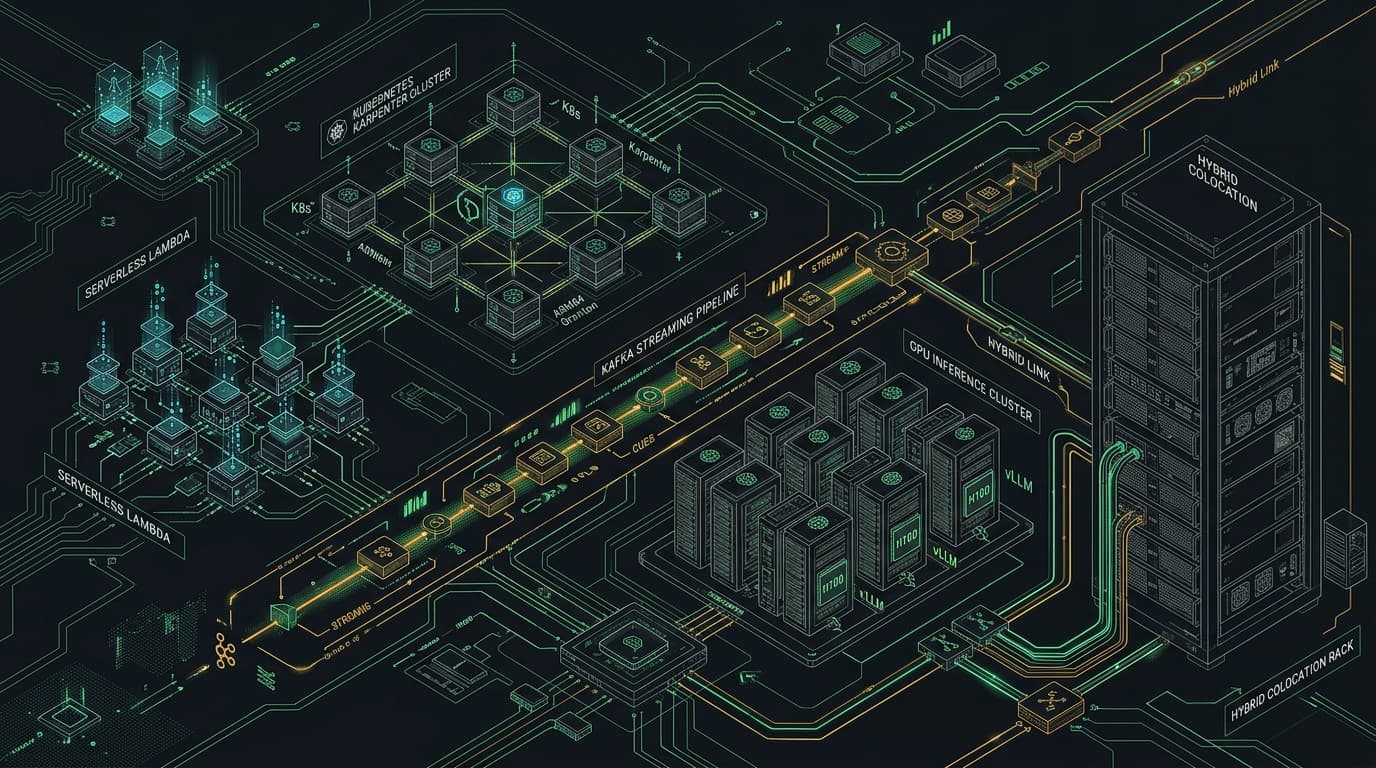
> ARCHITECTURE CATALOG // 18 MODELS
18 Cloud Architectures & Breakeven Curves
From serverless to bare-metal colocation across 54 maturity tiers with exact unit cost step-functions.
Managed Container Microservices on AWS ECS Fargate
Serverless container execution on AWS ECS Fargate eliminating EC2 cluster management overhead while providing predictable per-second resource billing.
Google Cloud Run Managed Microservices Platform
Highly elastic managed container platform scaling to zero when idle, billing exclusively during active request processing.
Azure Container Apps (ACA) Microservices Mesh
Fully managed serverless container environment built on top of Kubernetes and KEDA, providing Dapr microservice capabilities with consumption billing.
The TinyCTO Cloud Economics & FinOps Architecture Canon ('The Cloud Bill Bible') establishes an operational engineering discipline for cloud financial governance. Built upon the FinOps Foundation FOCUS 1.0 open specification, the canon details 18 production cloud architectures across 6 archetypes, 24 cloud waste typologies with detection queries and CLI remediation playbooks, a deterministic sizing wizard engine with itemized Bill-of-Materials calculations, 10 deep bilingual engineering manuals, and a 26-tool comparison matrix.
Cloud Architecture & Breakeven Curves FAQs
Why is Serverless Event-Driven API (Lambda + DynamoDB) cost-optimal below 8 million requests/month but disadvantageous above 25 million?
Serverless architectures charge strictly for execution duration (GB-seconds) and invocation counts, meaning zero idle cost when traffic is low or bursty. However, at sustained high throughput (> 25M requests/mo), the per-million invocation premium exceeds the cost of continuously running rightsized container instances (ECS Fargate or Kubernetes with Karpenter), where CPU cores can process thousands of concurrent requests at a flat amortized hourly rate.
How does the High-Density EKS architecture achieve an 82% bin-packing efficiency?
By combining Karpenter Just-in-Time scheduling with Graviton ARM64 node pools and Vertical Pod Autoscaler (VPA) recommendation engines. Pod resource requests are right-sized based on p95 historical utilization rather than developer estimates, and Karpenter selects instances whose memory-to-CPU ratios match aggregate pending pod shapes, eliminating stranded memory capacity.
What is the breakeven point between managed streaming (Amazon MSK / Confluent) and self-hosted ClickHouse / Kafka?
Managed streaming services charge hefty operational management premiums and high cross-AZ data transfer markups. Below 50M events/month, managed services save valuable platform engineering time. However, beyond 500M events/month, self-hosting Kafka with Tiered Storage (S3) and ClickHouse on NVMe instances reduces streaming and analytical storage costs by > 80%, saving tens of thousands of dollars per month.
How does Speculative Decoding reduce LLM inference costs by 2.2x?
Large target LLMs (e.g. Llama-3.1-70B) are memory-bandwidth bound during autoregressive token generation. Speculative decoding pairs a lightweight draft model (Llama-3.2-1B) running on cheap compute to propose 4-5 tokens per step. The large target model verifies all candidate tokens in a single parallel forward pass, achieving a 2x-2.5x speedup in throughput and slashing GPU duty cycle duration without any loss in generation accuracy.
How does the Hybrid Bare-Metal Egress Shield prevent cloud bandwidth lock-in?
By locating heavy storage, video streaming, or data replication workloads on dedicated bare-metal servers (e.g. Hetzner) connected via low-latency unmetered transit to Cloudflare or AWS CloudFront edge caches. Steady-state traffic consumes $0 unmetered bare-metal bandwidth, while public cloud compute is utilized only for elastic, stateless burst capacity.
Why is Debezium CDC preferred over recurring ETL batch queries for database synchronization?
Periodic batch ETL jobs run massive `SELECT *` table scans that saturate primary database CPU, spike read IOPS, and require oversized database instance tiers. Debezium Change Data Capture reads the database Write-Ahead Log (WAL) directly at the storage engine level with near-zero CPU overhead, streaming record inserts and updates continuously without degrading operational transaction performance.