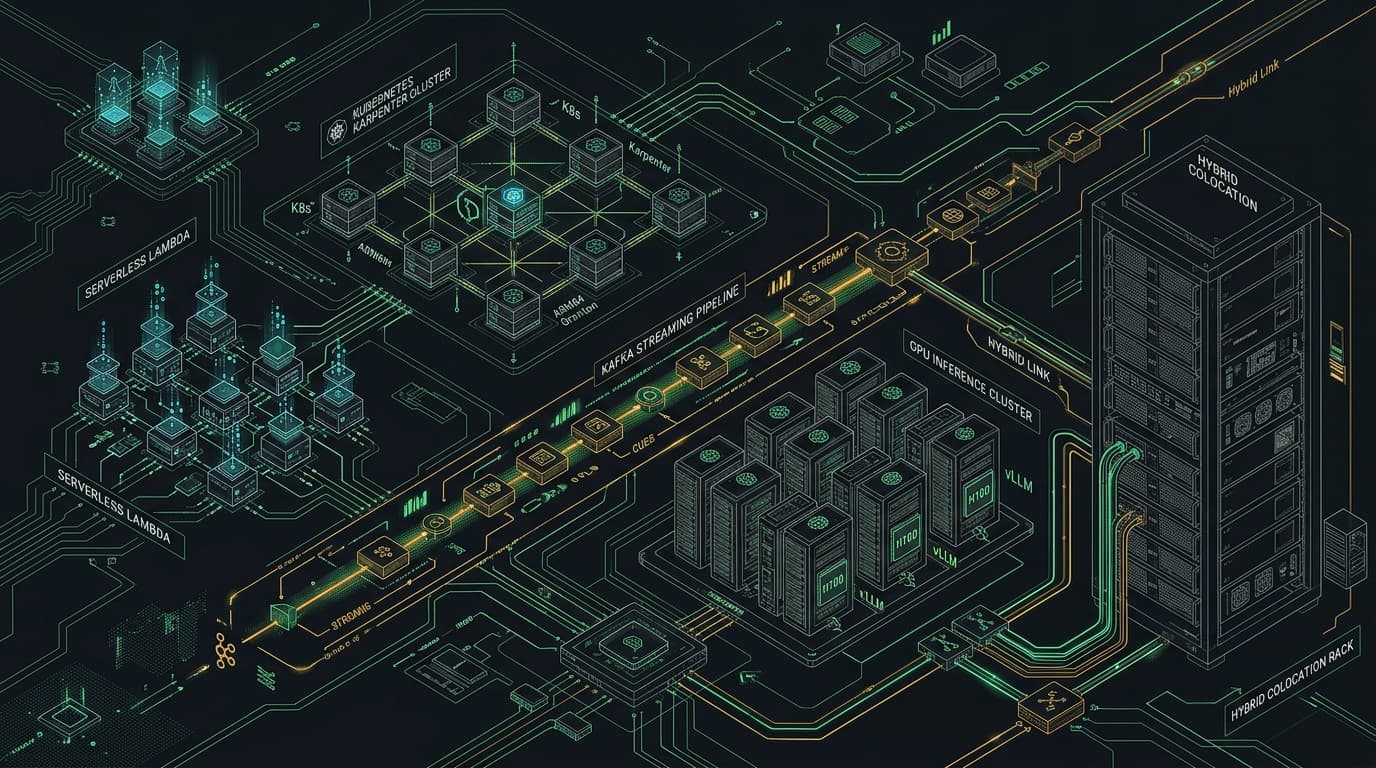
> GENAI_GPU
High-Throughput Vector Embedding Pipeline: GPU & CPU AVX-512
Asynchronous text embedding architecture combining GPU batch inference for high-volume ingest with CPU AVX-512 fallback for low-latency point queries.
Mathematical Breakeven Inflection Curve
Generating > 500 million embeddings/month self-hosted costs ~$800/mo vs $10,000+/mo on commercial embedding APIs (92% savings).
3 Maturity Tiers & Infrastructure Specifications
Component stack and cost steps from prototype to hyper-scale enterprise
1. Prototype / Early Stage10M - 50M embeddings/mo
$65 - $220 / mo
$0.0045 / 10K embeddings
Stack Components:
- 1x EC2 c7g.2xlarge (Graviton3 ARM64)
- FastEmbed / ONNX Runtime
- S3 Input Buffer
Cost Allocation:Service Tagging
Autoscaling:EC2 ASG CPU Target Tracking
2. Scaled Production100M - 1B embeddings/mo
$450 - $1,800 / mo
$0.0018 / 10K embeddings
Stack Components:
- 2x EC2 g5.xlarge (1x A10G 24GB)
- Triton Inference Server with TensorRT
- Redis Vector Cache
Cost Allocation:FOCUS Embedding Pipeline Tagging
Autoscaling:SQS Queue Length Autoscaler
3. High-Throughput Enterprise1B - 10B embeddings/mo
$1,800 - $7,500 / mo
$0.0007 / 10K embeddings
Stack Components:
- Kubernetes Cluster with 8x L4 GPU Spot pool
- Triton Model Ensemble with Dynamic Batching
- S3 Express One Zone shared dataset cache
Cost Allocation:Dataset & Ingestion Pipeline Allocation
Autoscaling:KEDA Metrics Server with GPU Duty Cycle Autoscaling
Key Cost Drivers
- •GPU compute hours during mass embedding backfills
- •Network transfer from document store to embedding nodes
Waste Vulnerabilities
- •Re-embedding identical documents repeatedly due to lack of content-hash caching
- •Running full float32 precision instead of int8/fp16 quantization
Mitigation Playbooks
- •Enforce SHA-256 document hashing with Redis cache lookup
- •Quantize embedding models to INT8 using ONNX Runtime (3x speedup, 75% memory reduction)